Lambert, who has met researchers at the Chinese open-model labs, says they are technically excellent and roughly equal in talent to US labs, but far more compute-starved. He is skeptical that distillation from US models explains much of their progress.
…was released, we talked about consolidation in the industry and predicting it. And I think we're just starting to see a much more active mergers and acquisitions market. But I thought this was going to happen two years ago. And the open model companies have lasted much longer than I thought.
…the Chinese labs, since you've actually met with them and you've studied this a lot more, is it sort of like they're all-rounded, like great at pre-training, also have their own good post-training recipes that they may or may not have revealed. And where do you see the levers kind of accelerating?
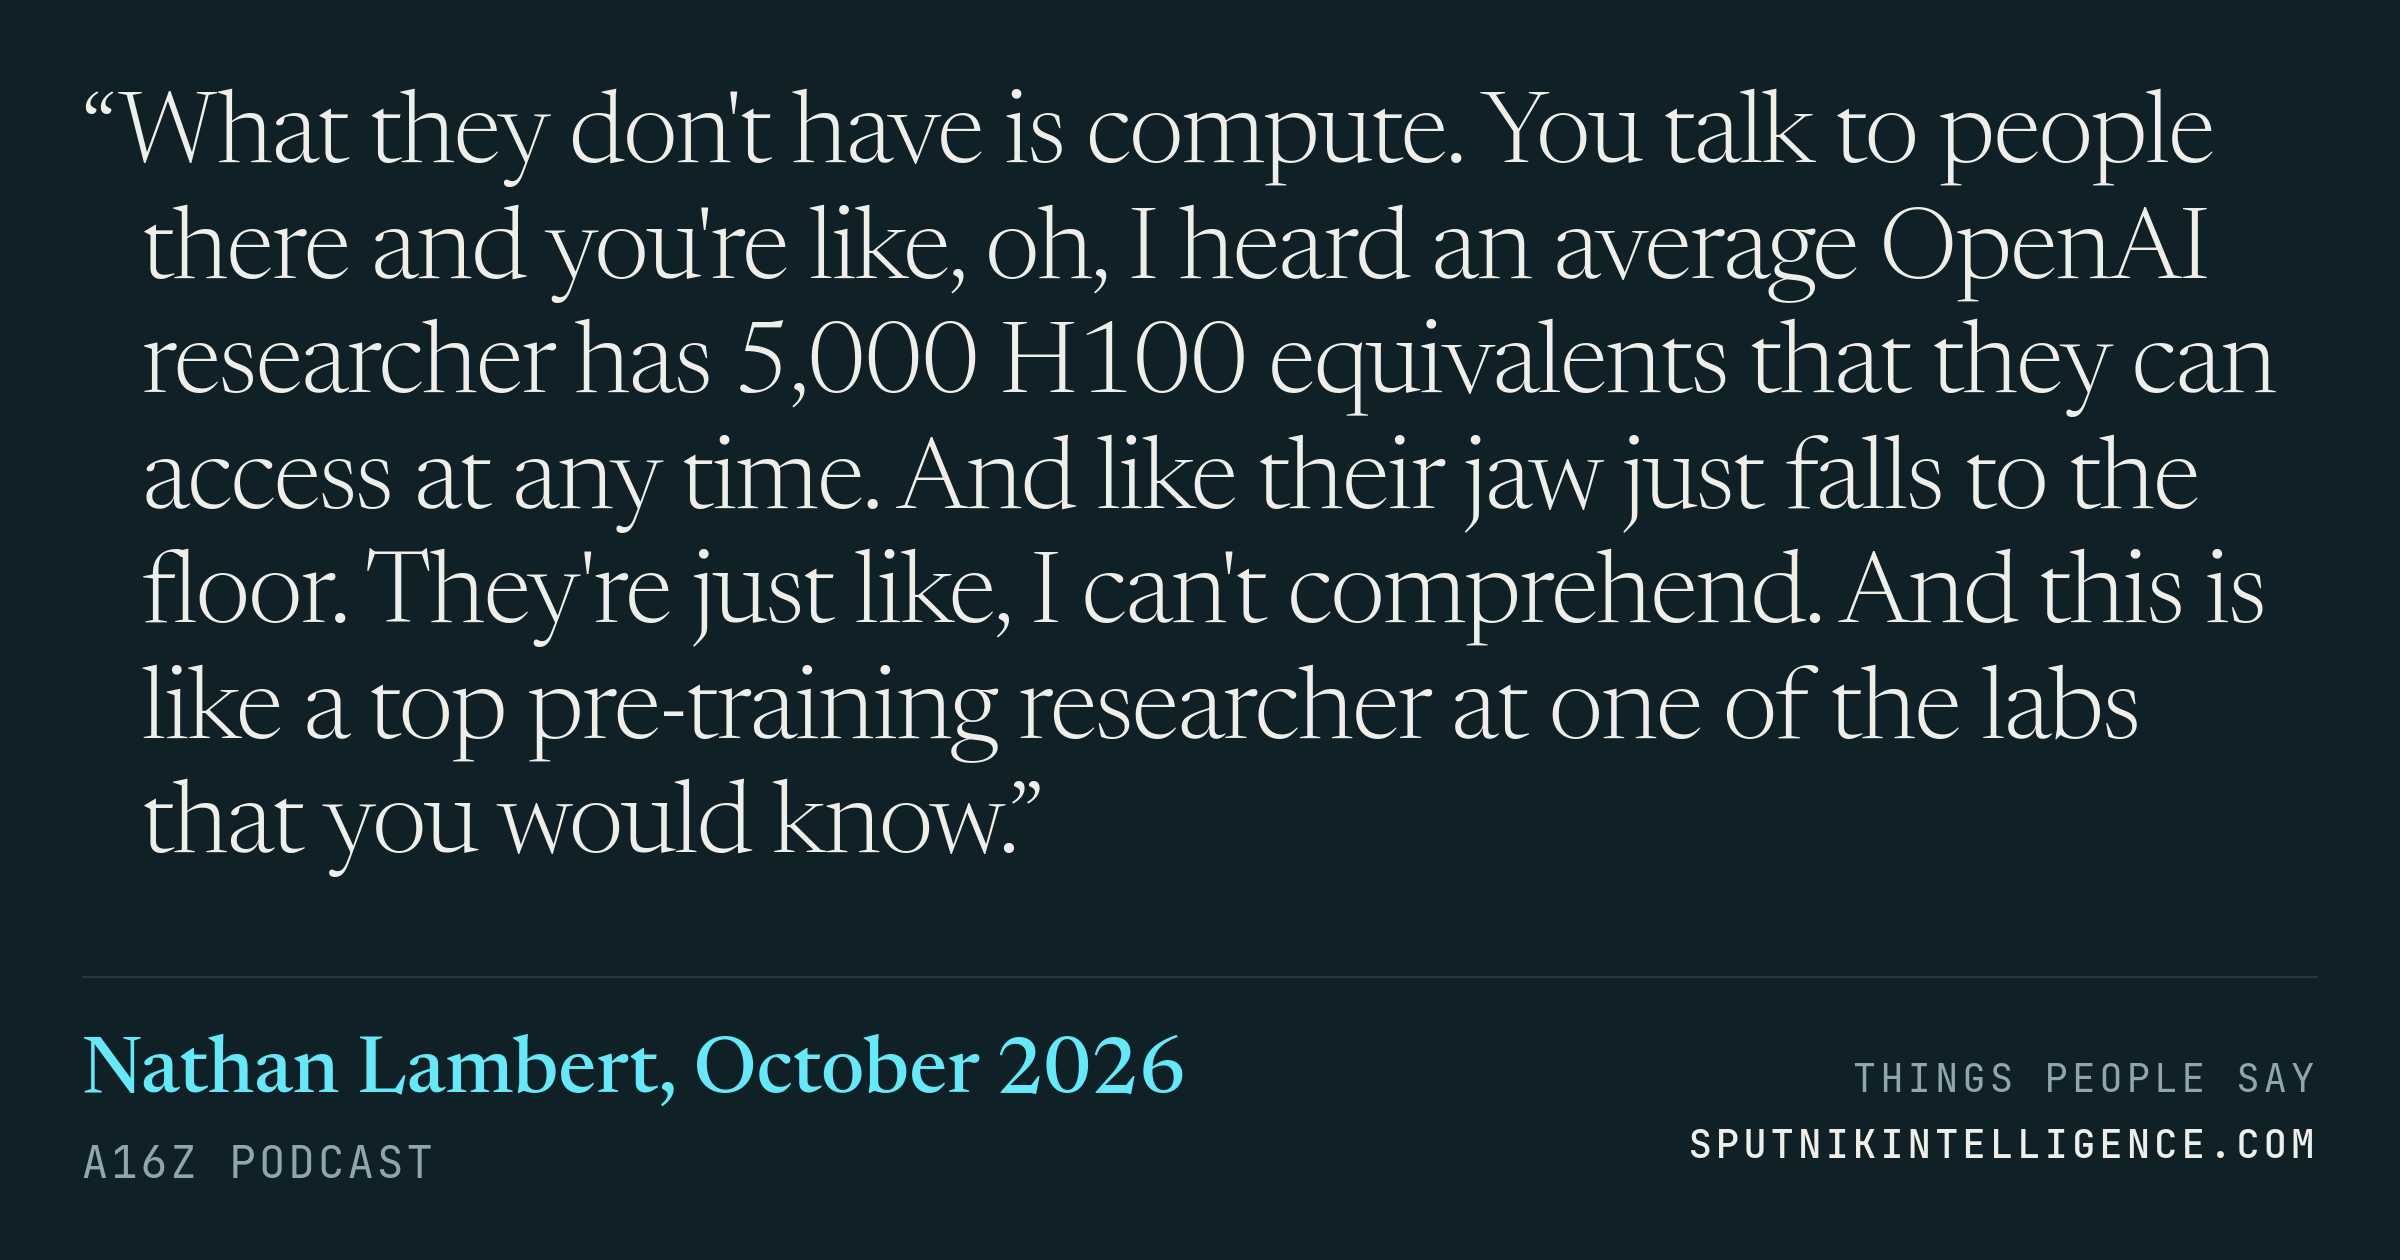
Yeah, so the Chinese labs are very technically excellent. They are more compute-starved. I think without a doubt, they have a comparable talent pool to draw on. I think there might be like a slight edge based on who was where when AI really got going. But to say that China is anything but equal in talent, you're going to have a hard time because they just have so many people being trained at such a high level. And what they don't have is compute. You talk to people there and you're like, oh, I heard an average open AI researcher has 5,000 H100 equivalents that they can access at any time. And like their jaw just falls to the floor. They're just like, I can't comprehend. And this is like a top pre-training researcher at one of the labs that you would know. And then you have this interaction a few times. And the compute thing, I think, is the biggest difference. And Distillation is a way to effectively spend more money to get what is compute equivalent. Like outputs from a language model are a function of compute. And if you know the outputs you want, it's the same as having compute to generate with a model. And I've seen the…
how is that? There
are so many companies. There's like 20 to 30 companies that are building good models. You can like read. Yeah, yeah. And it's like, you just, and like, it's hard for me to get over. And I think that there's this very prominent paper that says like stealing reasoning traces from closed models. And I…
Right. So that's